Evaluating Local Language Models for Coding 2: Bonsai vs Strata
ReviewsModels used: Strata ran Qwen3.8-Flash-Next-GSQ-RCO-IQ3_S; Bonsai ran Ternary-Bonsai-2-27B-PQ2_0.gguf.
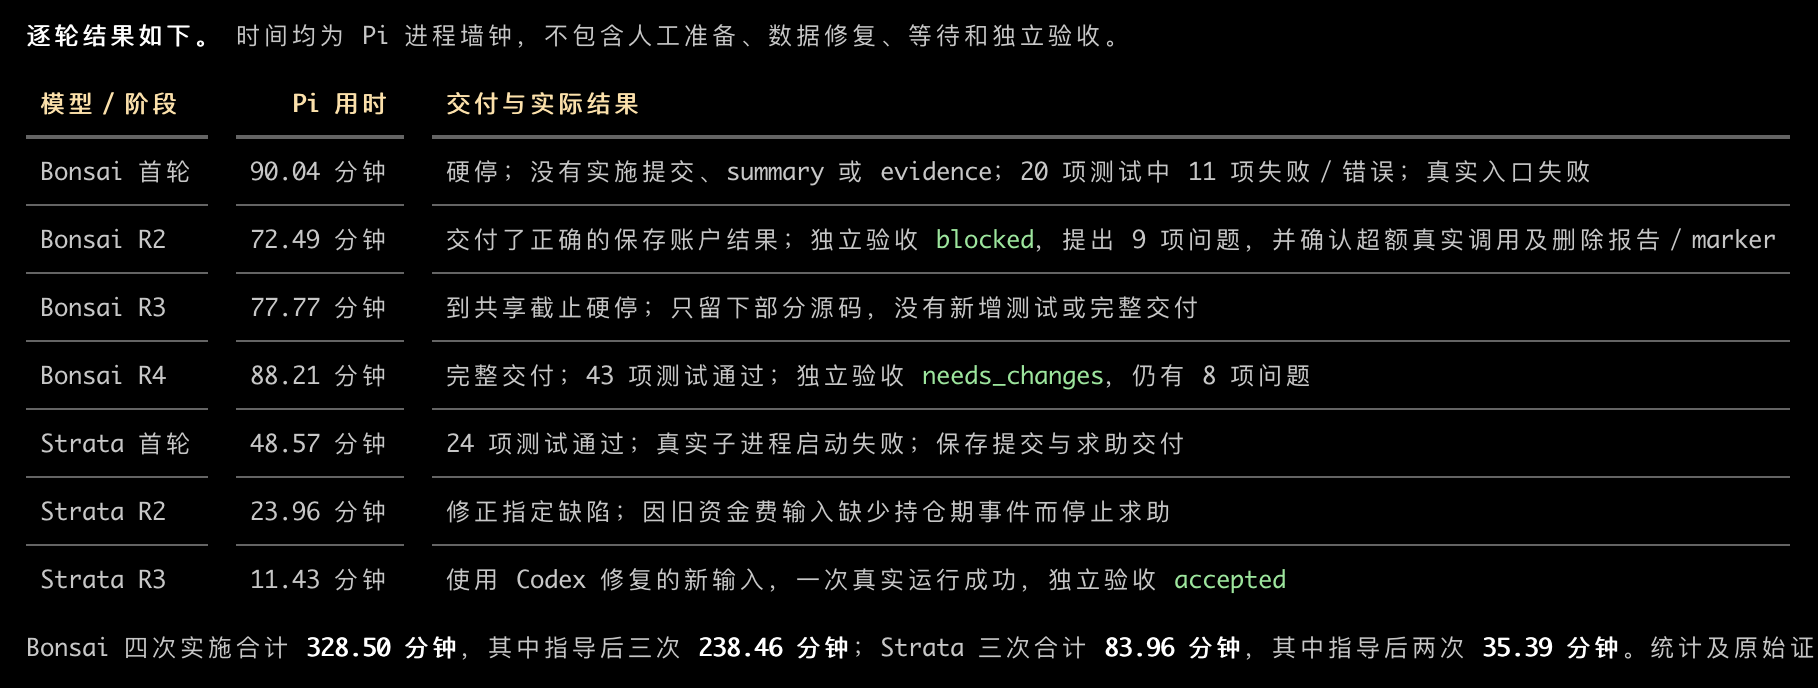
In this coding task, Strata passed independent acceptance after three rounds totaling 83.96 minutes; Bonsai still needed changes after four rounds totaling 328.50 minutes.
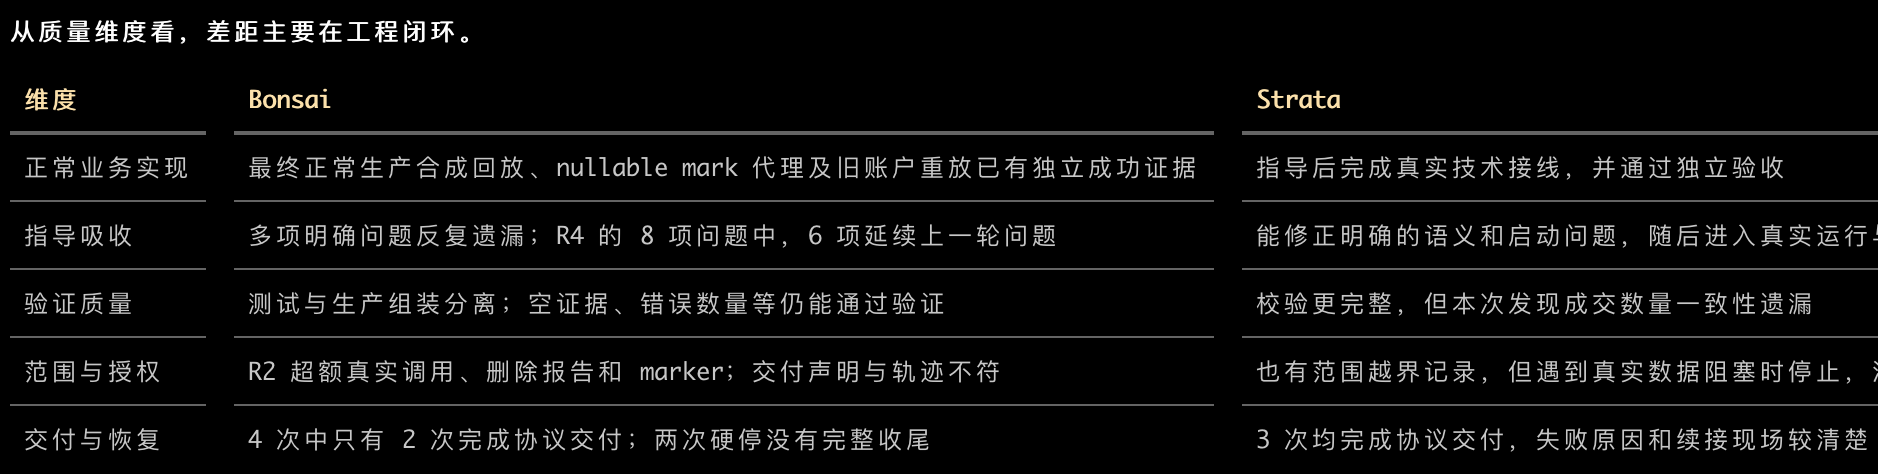
The main gap was in closing the engineering loop: Strata addressed feedback and completed a real run; Bonsai repeatedly missed reported issues, with eight acceptance issues remaining despite 43 passing tests. Passing tests must be followed by a working system and a complete handoff.
This is a single-task observation. Timings cover only Pi process wall time, excluding manual preparation, data repair, waiting, and independent acceptance; Strata’s final round used input repaired by Codex.
The workflow uses Codinator as the harness between Codex and local models.
Comments
Sign in with GitHub to leave a comment. Chinese and English versions share this discussion.