Evaluating Local Language Models for Coding
ReviewsBackground
Since Codex released its 5.6 and 6 models, token consumption has been too high, so I tried using local language models for coding tasks. The two models tested were:
Both models worked reasonably well in initial use. PrismML Bonsai has a small resource footprint and runs smoothly on an NVIDIA 3090 GPU. The coding tasks come from the KMesh project.
Evaluation Method
- Use Codex 6 (xhigh) to plan the task and prepare a handoff document.
- Have the local model (Qwen or Bonsai) execute the task based on the handoff document and perform the required checks itself.
- Have Codex review the local model’s results and provide feedback if revisions are needed.
- Pass the review feedback to the local model for revisions, then submit the results to Codex again. Repeat until the task passes review.
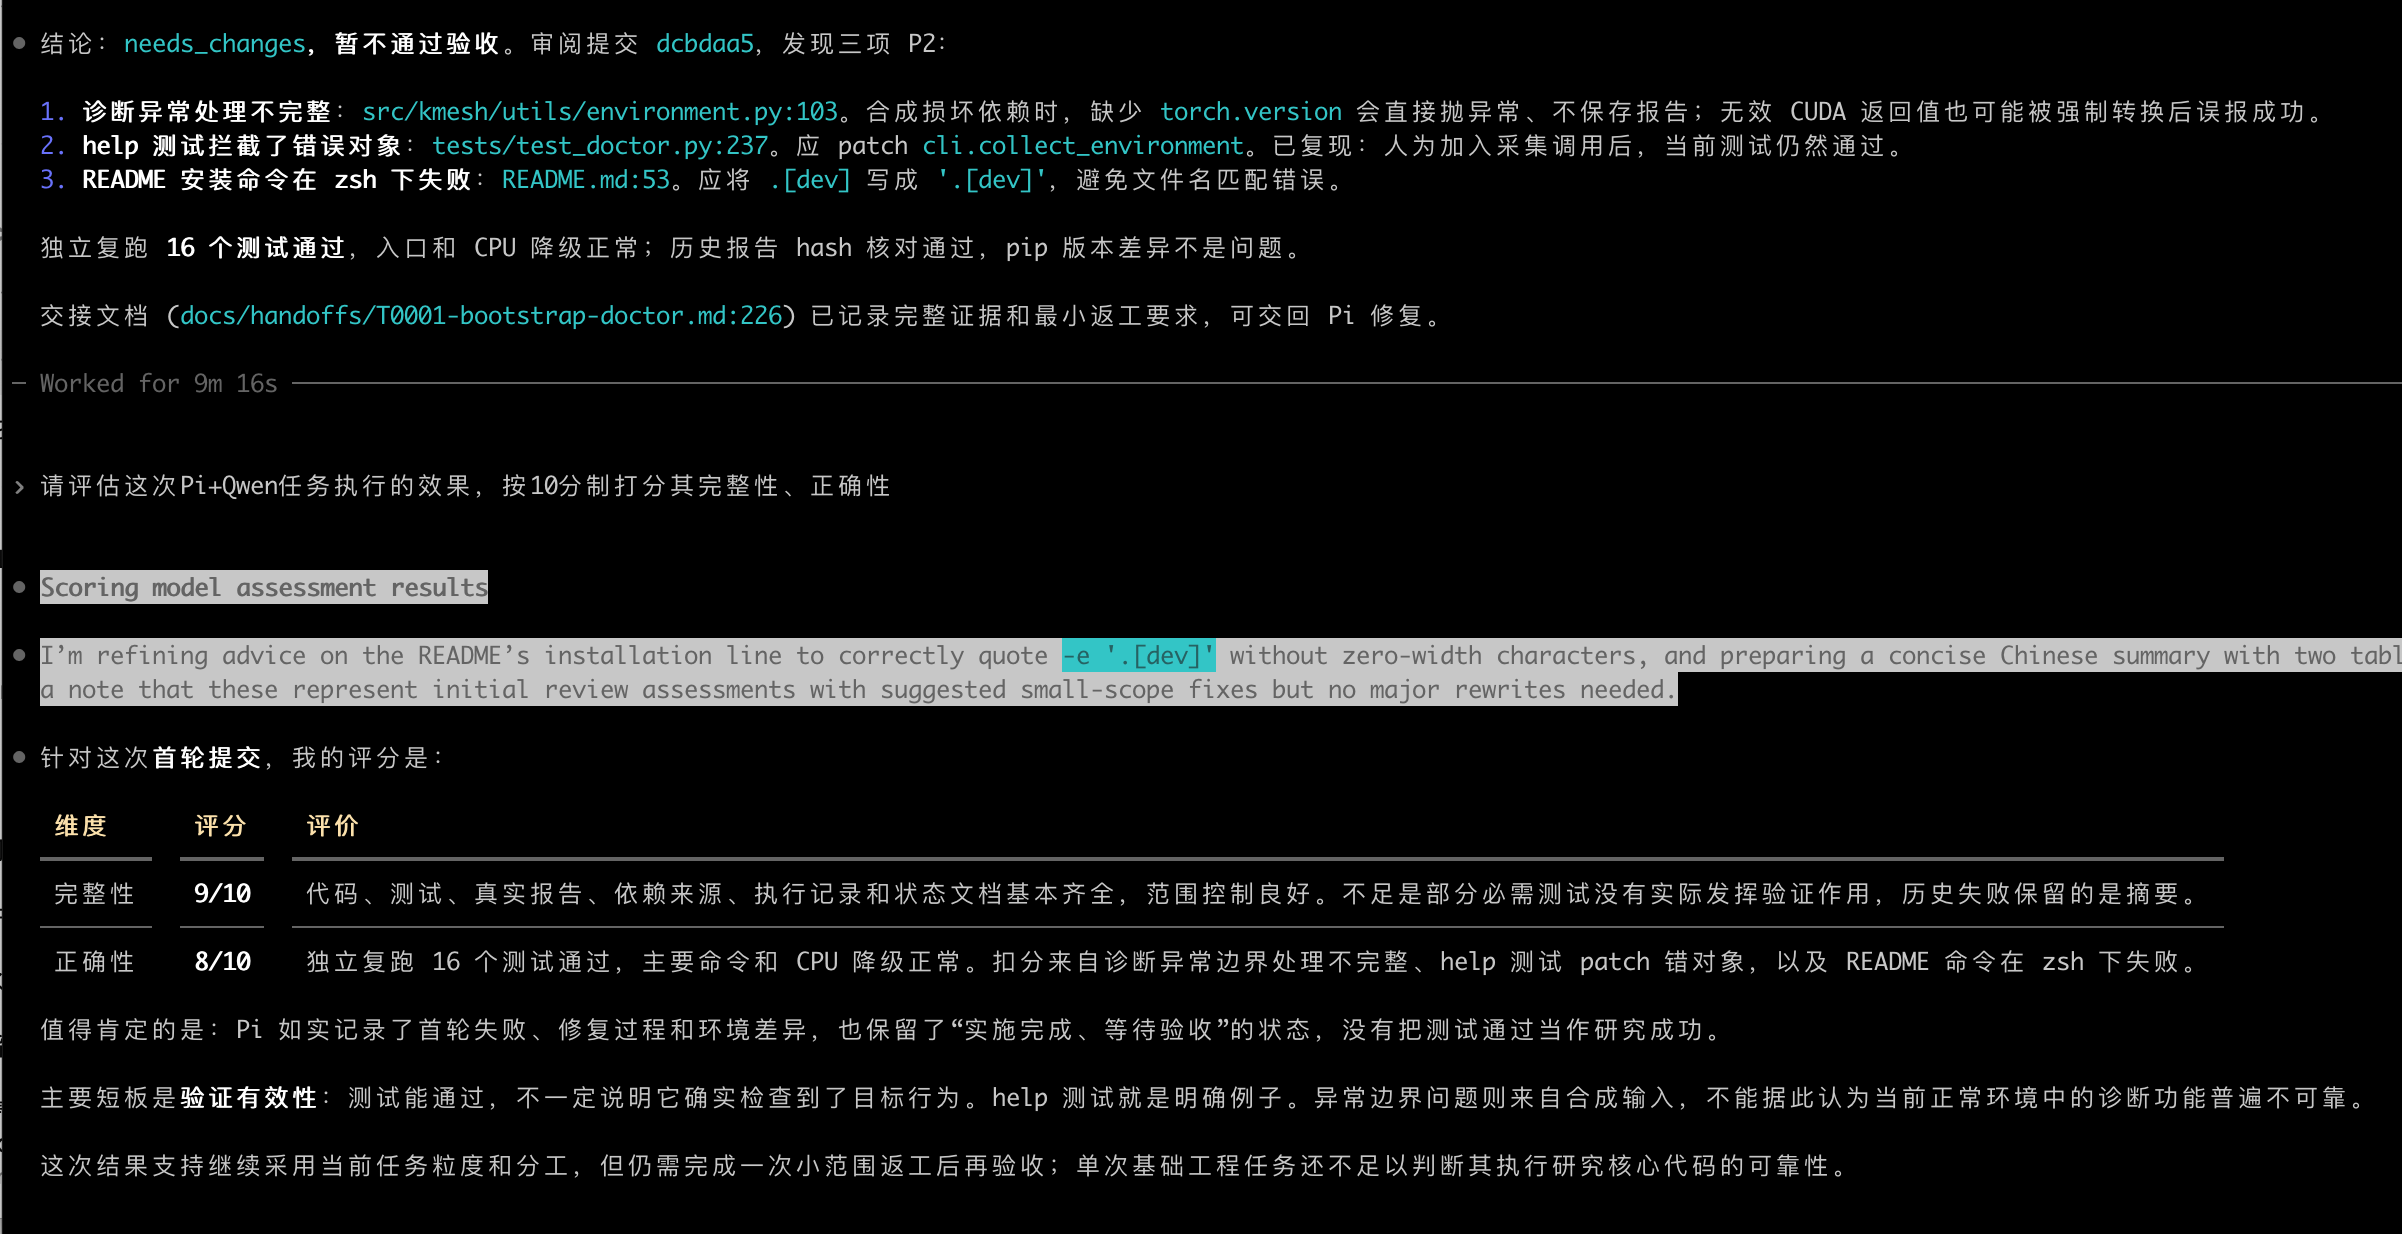
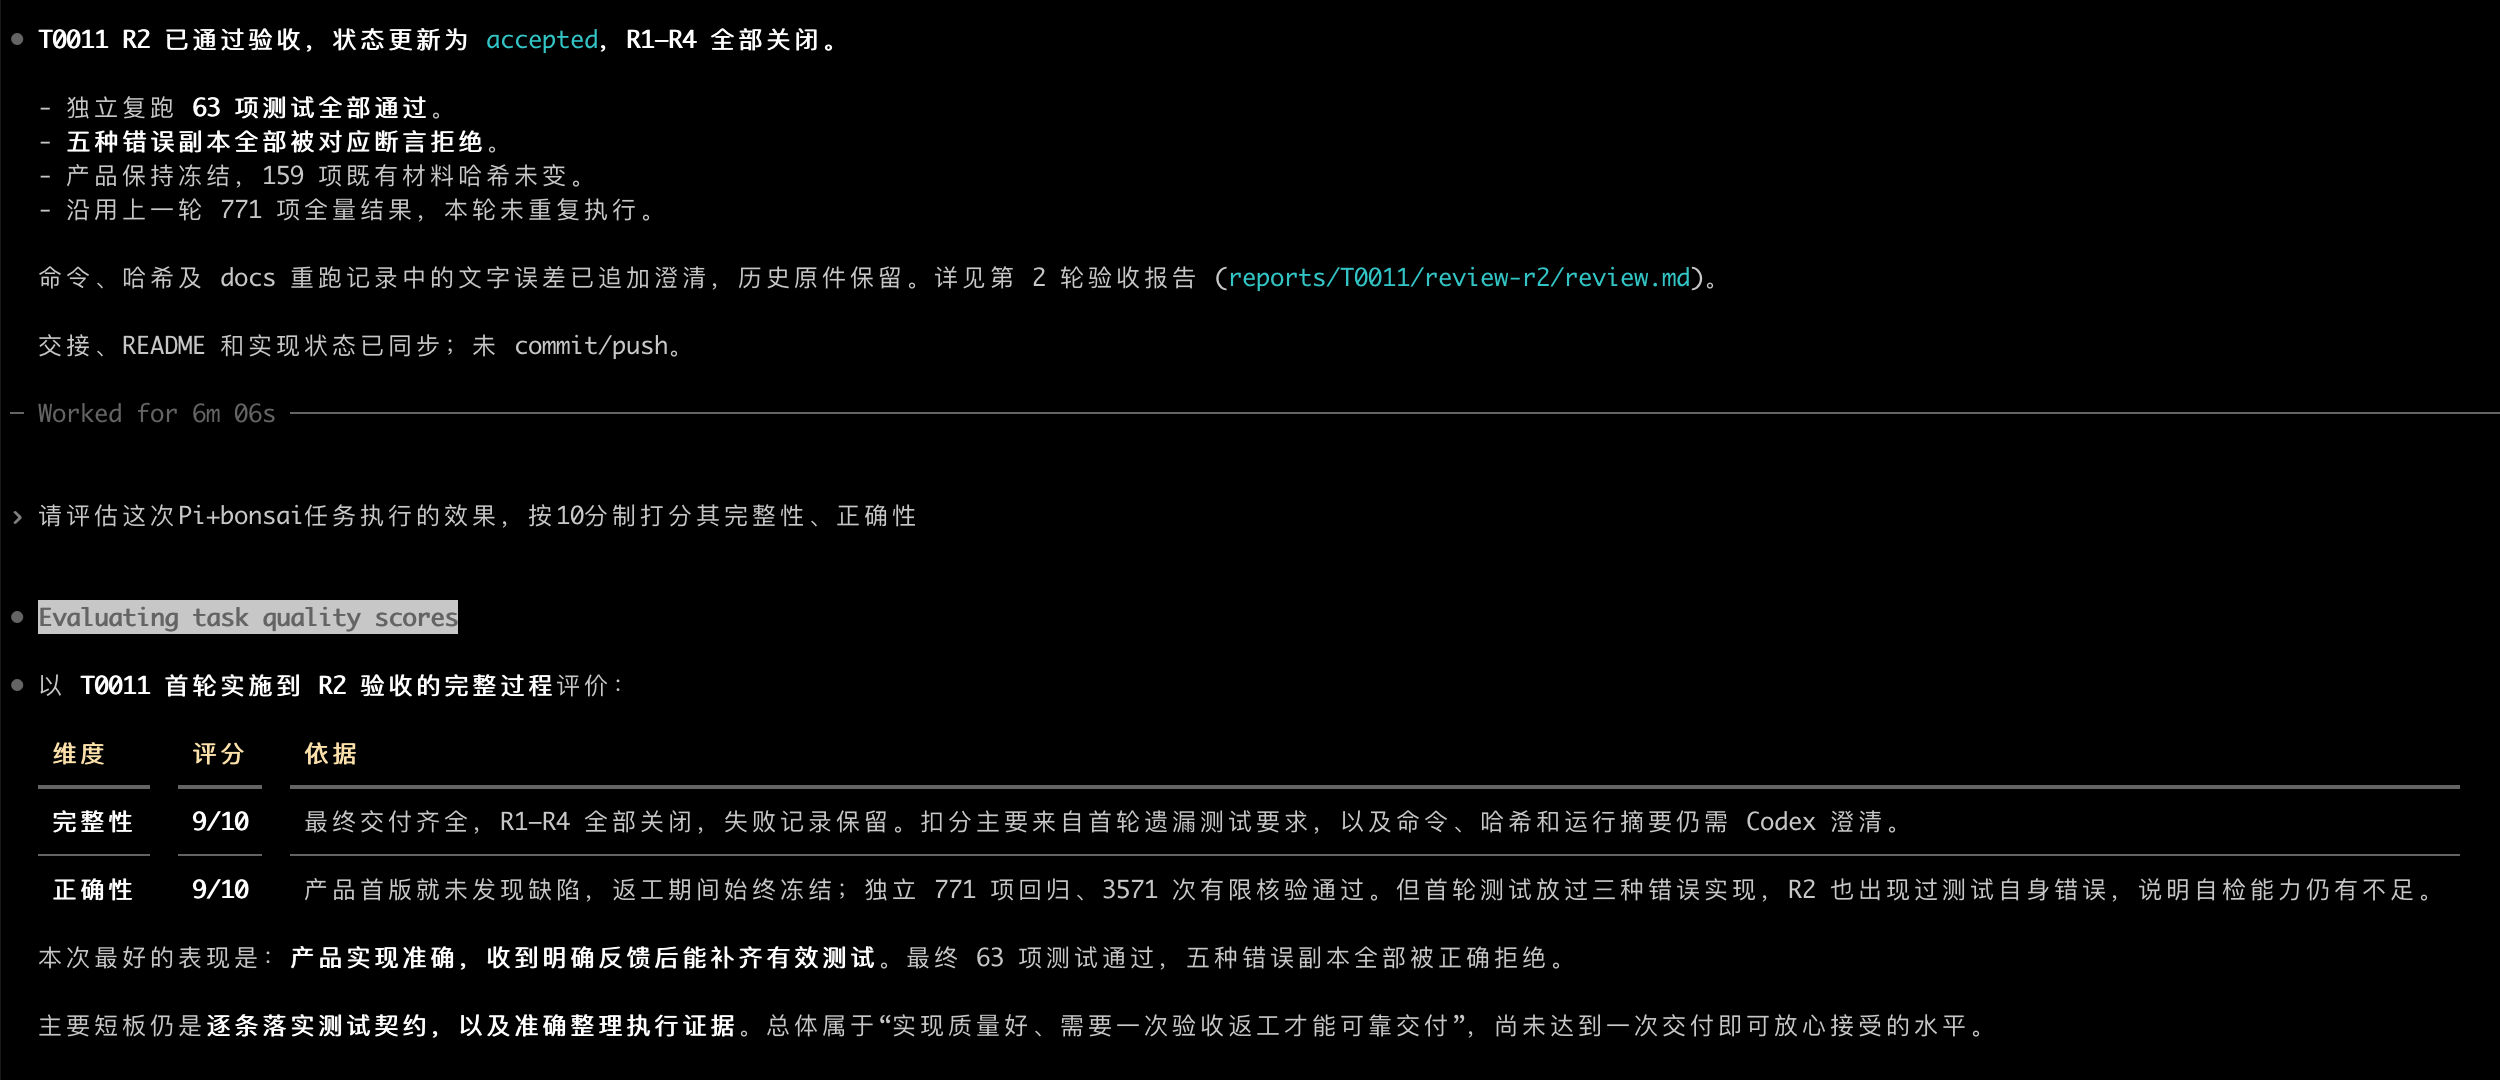
- Ask Codex to assess the completeness and correctness of the local model’s work across the full execution and review cycle.
Qwen Evaluation Results
Bonsai Evaluation Results
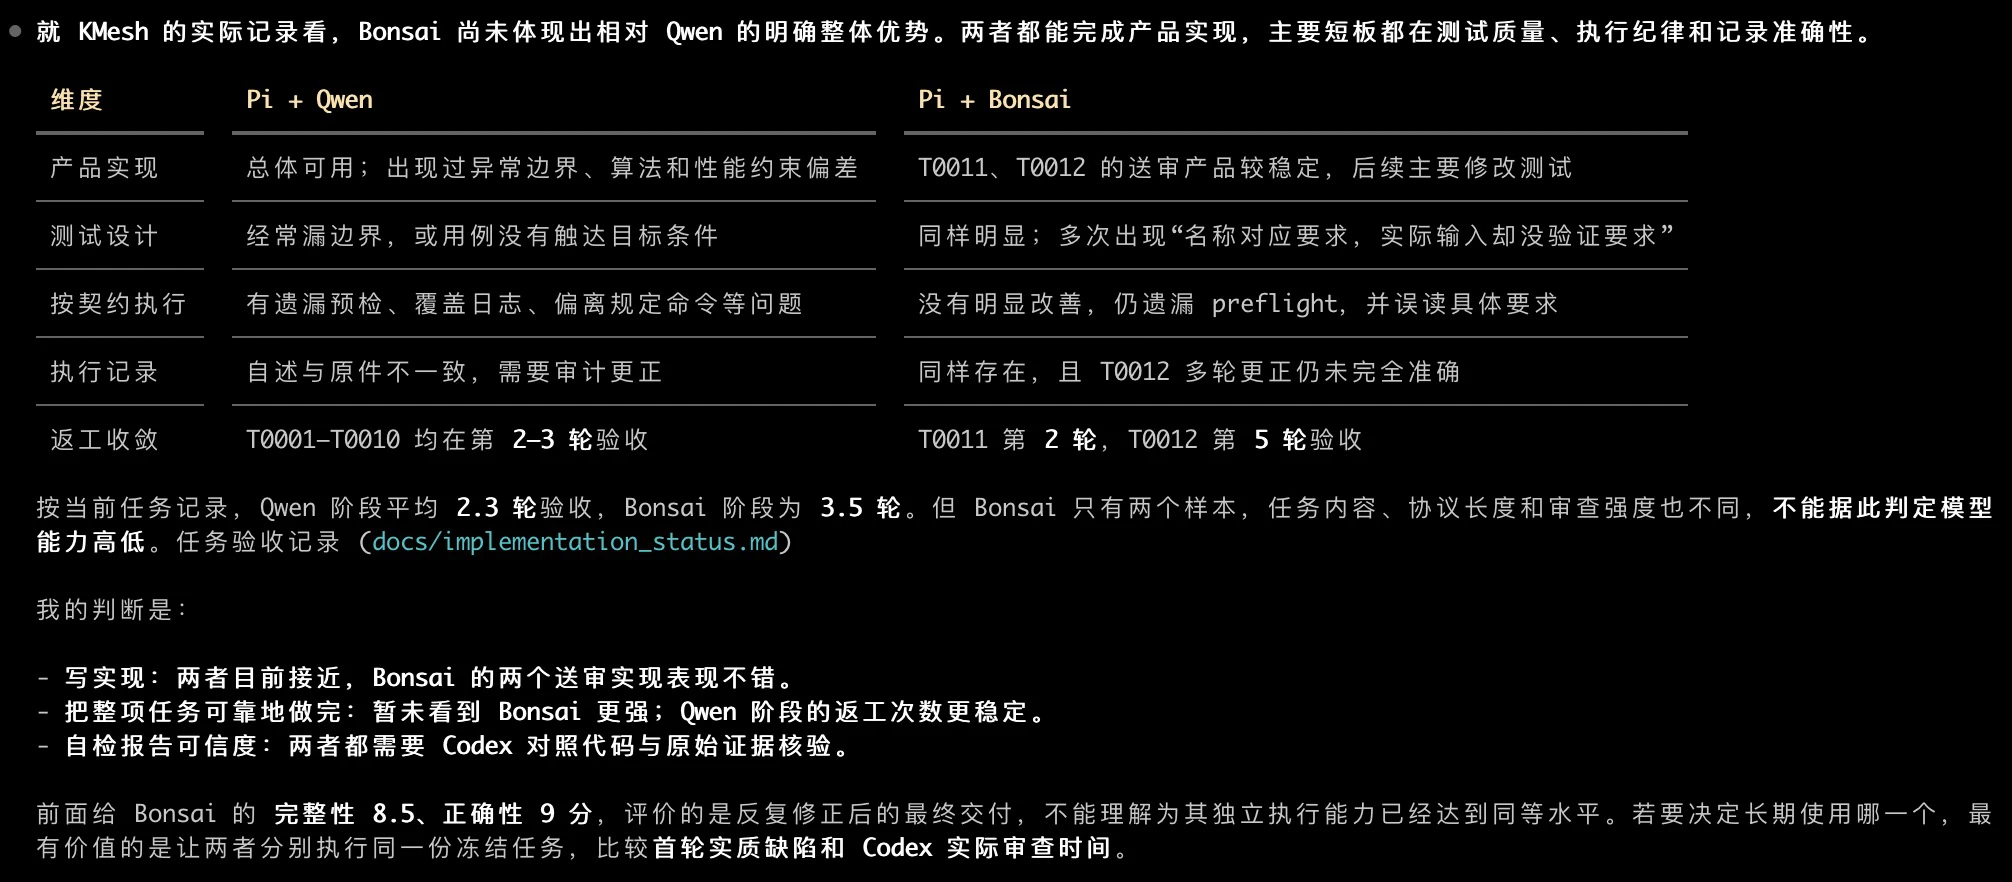
Qwen vs. Bonsai Comparison
Comments
Sign in with GitHub to leave a comment. Chinese and English versions share this discussion.